Grouped by what it changes for you.
Not a wall of claims — researched pages in a consistent style, grouped by the axis they move: what the problem is, how veizik handles it at a reader’s level, the figures measured, and a reproduction guide. Every figure is veizik’s own, measured and reproducible; a more specialised engine may do better on a given case, and that is said where it applies.
The axes the field competes on — and where veizik leads.
Local-inference engines compete on a handful of axes: fitting a big model on a small card, how few bits at what quality, load time, long-context decode, video memory, dependencies and reliability. Here is the usual path on each, next to veizik’s own measured result.
The left column is the common path these systems take, stated as a widely documented convention — no engine is named and no other engine’s figure is quoted. The right column is veizik’s own measured result, each one reproduced on the capability page it links to. These are strengths, not verdicts: a more specialised engine may do better on a given model or card, and that is said where it applies.
One runtime, across the fleet.
The same native engine drawing on a datacentre card, a Jetson and a Raspberry Pi.
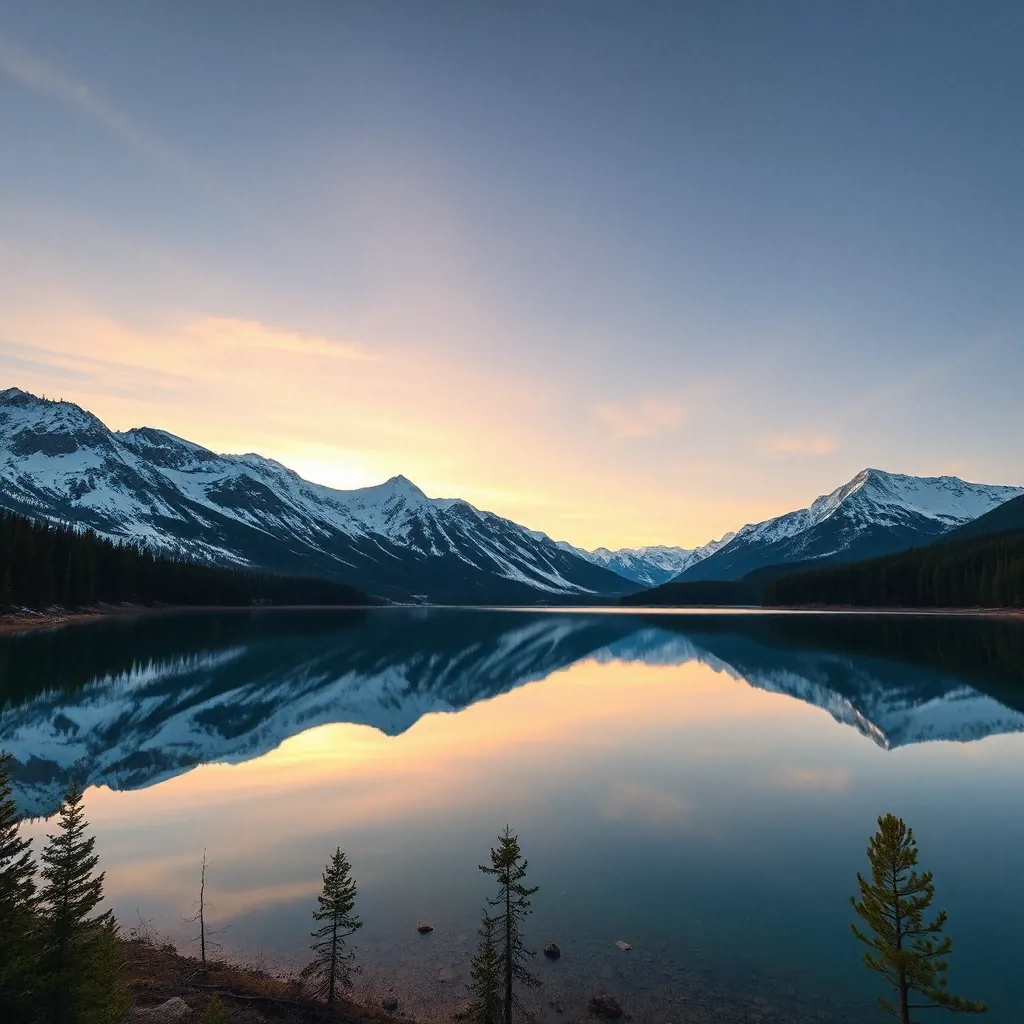
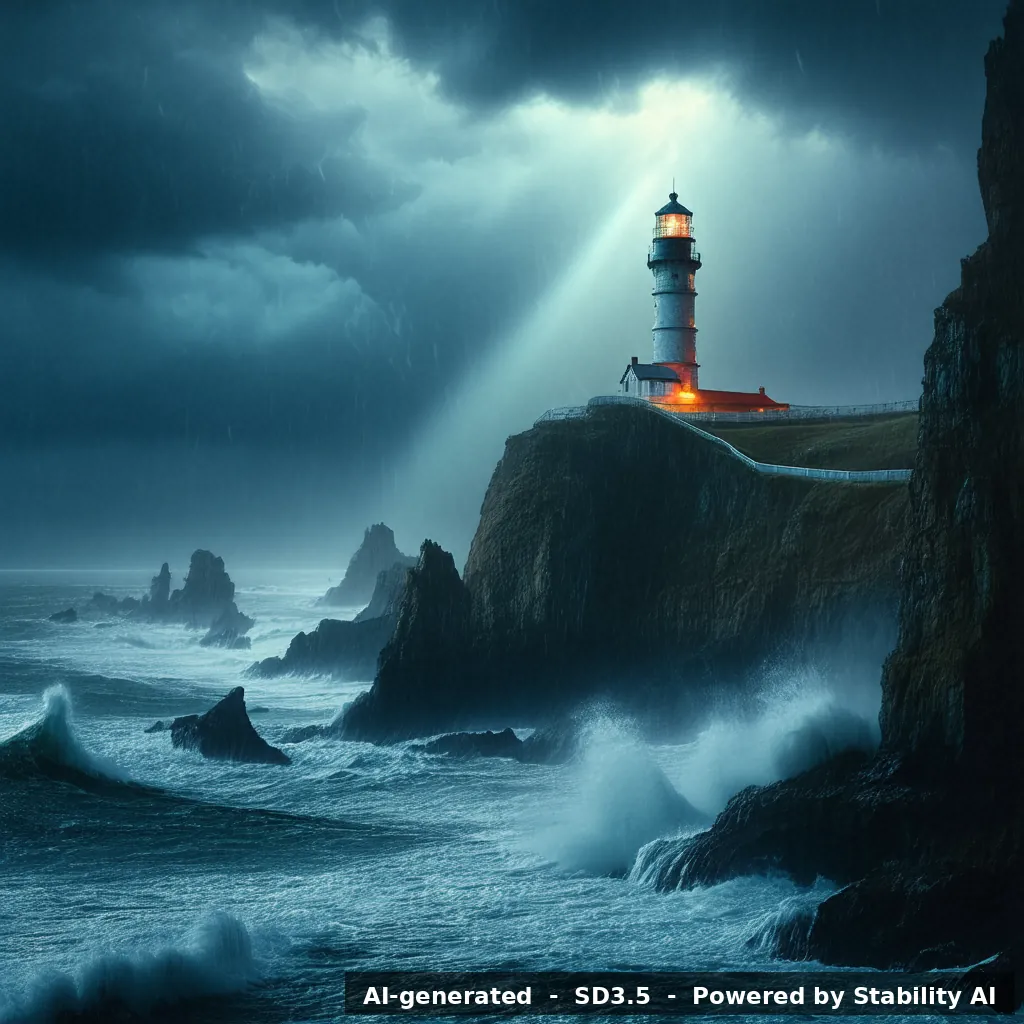
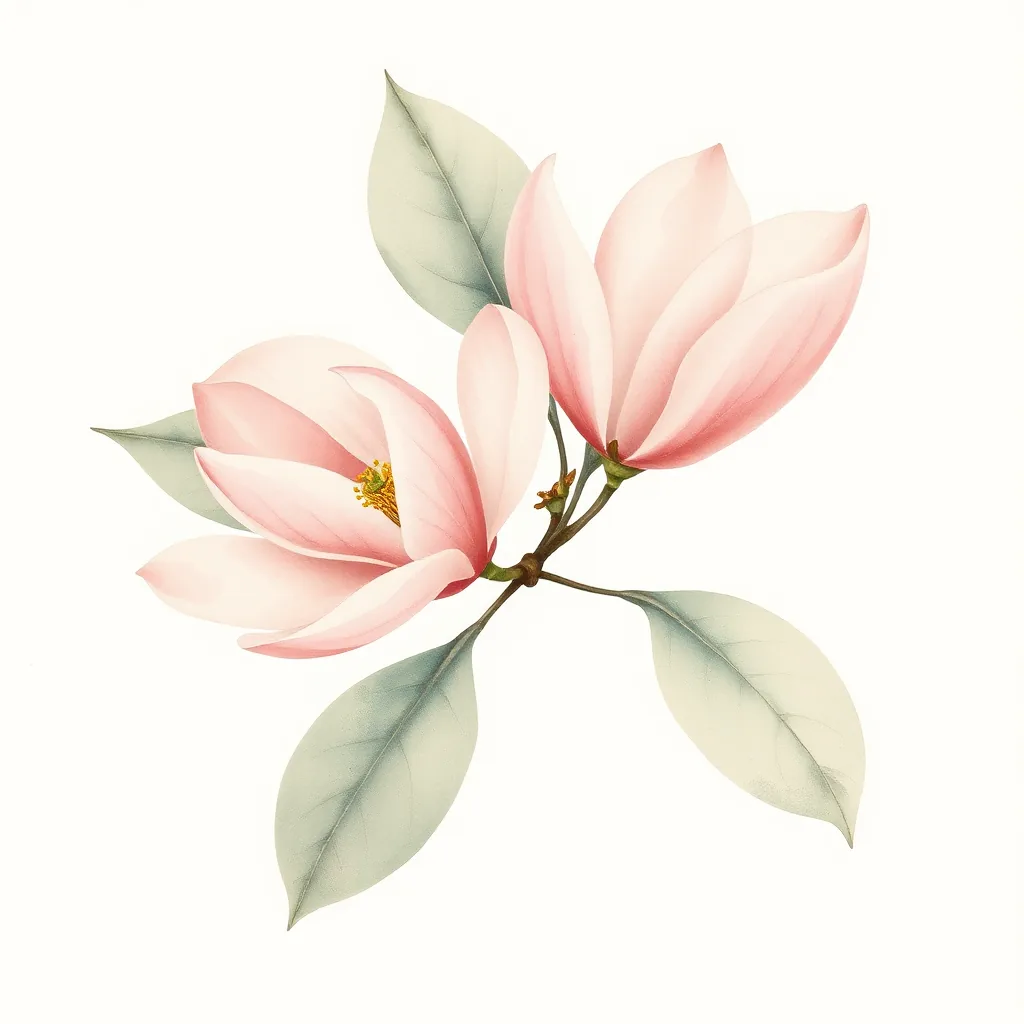
Drawn natively by Veizik on an NVIDIA RTX 3090, a Jetson AGX Orin and a Raspberry Pi 5 — output, not a benchmark. Powered by Stability AI.
The experience
Start to finished render — what the product feels like to use.
Precision
How few bits, at what quality — one artifact, many execution modes.
Memory & long context
Big models on small cards, and decode that holds as the prompt grows.
Video · memory
Video that doesn’t run out of memory
Why peak VRAM stays under a 24 GB card through a 720p WAN render — bounded working set, only the active experts resident, no prompt-driven spike.
Read · under 24 GB →Language · single GPU
A 35B MoE on one consumer card
A 35-billion mixture-of-experts model resident on a single 24 GB card in about 21 GiB — no second GPU, no CPU offload — decoding at 194 tok/s on an RTX 3090.
Read · 21 GiB on 24 GB →Language · long context
Decode that holds at a long prompt
Decode stays near-flat out to 16K tokens on a consumer card, and past 128K on a datacenter one — a measured rate at each length, not a spec-sheet maximum.
Read · 128K tokens →Image · low memory
A 12B image model on a small card
An image model that fits a small card by trading memory for speed, with per-architecture GPU code that needs no compile step at render time. Image generation ships today on NVIDIA; this measured write-up follows.
Coming →Loading & reliability
Resident in a heartbeat, and a render that resumes to the same bytes.
Loading
A big model, resident in a heartbeat
The slow part is often the load, not the compute. veizik’s hypercache restores a prepared, resident model instead of loading it cold — a 122B model answers in about 6 seconds on one RTX 3090, a language model in 14 ms on a Galaxy Note10.
Read · cold vs hypercache →Reliability
Resume a render, exactly
A render cut off five times — twice by a host crash — resumes from its last step and finishes to the identical latent hash.
Read · same SHA-256 →Hardware reach
The same engine, from a datacenter GPU down to a Raspberry Pi.
Hardware · edge
Generative AI on a Raspberry Pi
The same engine, down to a Raspberry Pi 5 and a 512 MB Zero 2 W — image, video and language models on the CPU alone. Sub-byte quantization and a native, compile-free kernel path do the work of a GPU that isn’t there.
Read · on a Pi CPU →Hardware · thermal
Power, clock and thermal, under control
A sustained render heats a CPU until the firmware throttles it hard — mid-render, into a reset. A reactive governor caps the clock ahead of that point, with explicit power modes and a supervised overclock, so the render completes. Measured on the boards.
Read · under 76 °C →Independence
What the engine runs on — and, just as important, what it doesn’t.
Pages are published as each is researched and measured. No competitor is named, and no implementation detail is given — only what a reader can hold and reproduce.