NVIDIA
Available now
Runs Language, Image and Video
- Ampere
- Ada Lovelace
- Hopper
- Blackwell
Independent AI execution engine
AI execution, re-engineered. One runtime across models, architectures and hardware — language, image and video, executed natively from the checkpoint you already have, with nothing else to install.
Suggested for this device. Pick another platform any time.
curl -fsSL https://veizik.com/install.sh | sh veizik install wan22 veizik activate veizik pull wan22 veizik run wan22_t2v_a14b "<your prompt>" --out ./clip # frames are written to ./clip/frames/
# Apple Silicon · macOS (arm64) ./install.sh veizik run qwen2.5-1.5b-instruct "In two sentences, what is a safetensors checkpoint?" --tokens 96
A safetensors checkpoint is a file that contains the weights and biases of a neural network model, which are used to train the model and generate the model's output. The safetensors format is designed to be more efficient and portable than the original TensorFlow checkpoint format, and it allows for better compression and storage of the model's weights. It is commonly used in the field of machine learning and artificial intelligence to save and load neural network models.
# Edge · Raspberry Pi curl -fsSL https://veizik.com/rpi/install.sh | sh veizik run smollm2_135m "The capital of France is" --mode balanced
Paris
Start with the task. Each one opens the models that support it, with the devices and builds they run on.
Chat, complete and serve language models on your own machine, with a local OpenAI-style endpoint when your tools need one.
See language models →Turn a text prompt into a still image on your own GPU or edge board, from a published checkpoint.
See image models →Render text-to-video and image-to-video clips locally. Frames are written to a folder you choose.
See video models →Each result was rendered by VEIZIK from a published checkpoint. The caption names the model, the device and the build that made it.
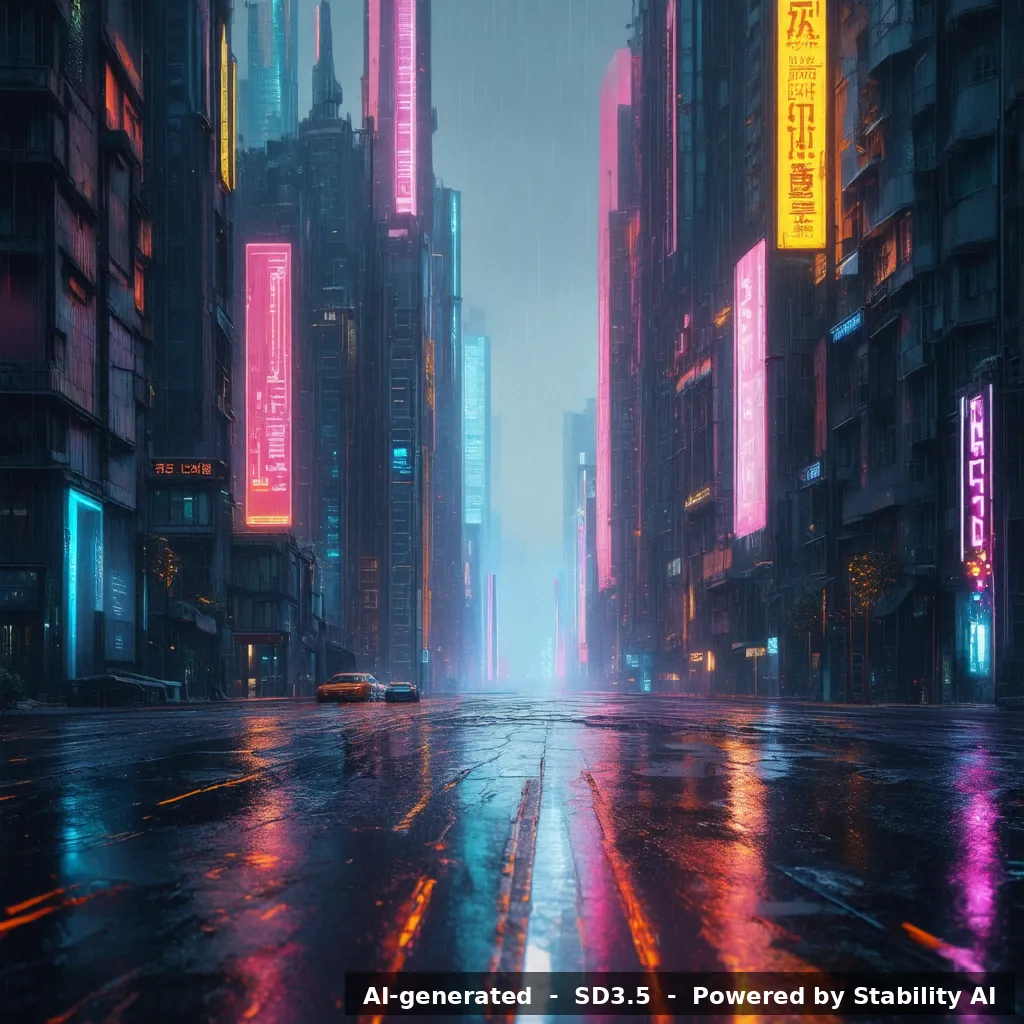
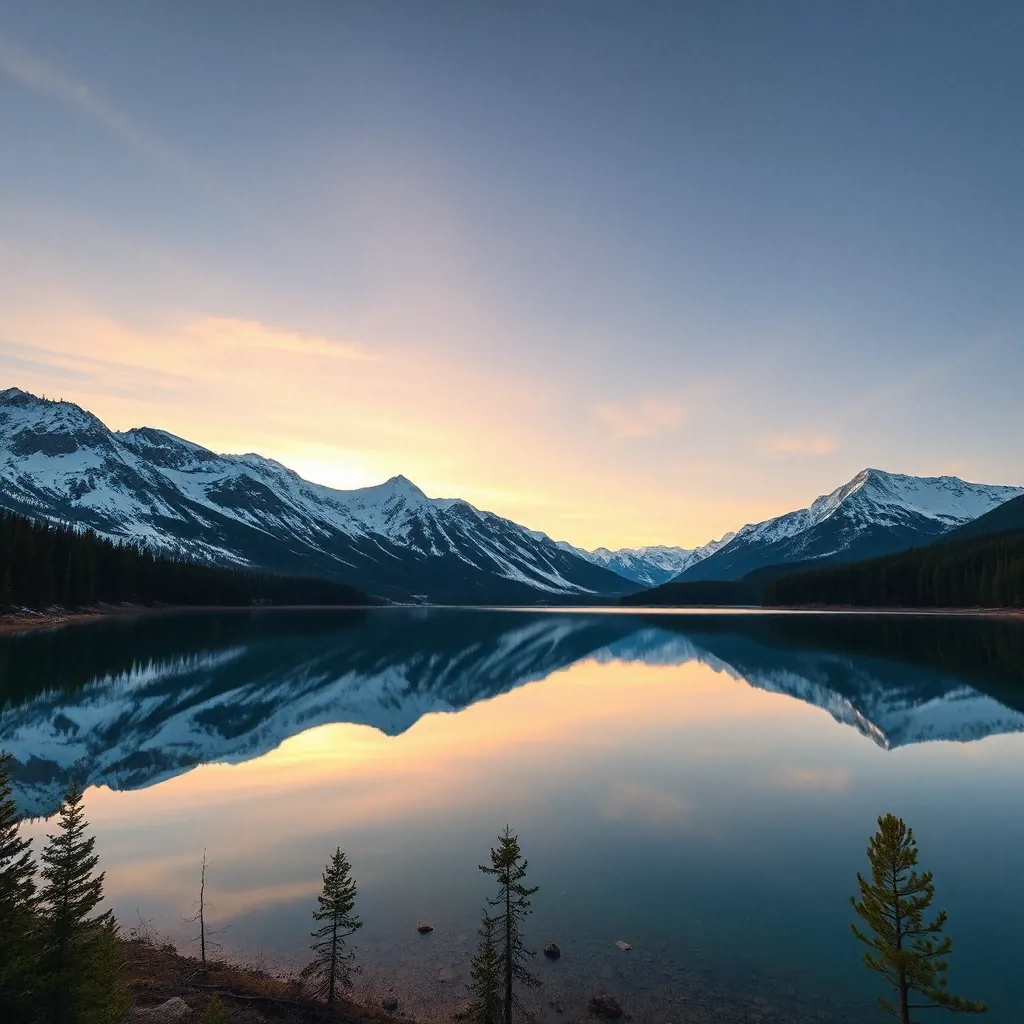
Use a native runtime without a Python or deep-learning framework installation on supported deployment paths. VEIZIK compiles and runs the model itself, on the GPU or CPU you have.
Read about the product →Start from supported published checkpoints. Weights come from their publishers and stay under their licences. Review each model’s requirements before you run it.
See supported models →Generation runs on your hardware, so prompts and results stay on your machine. Check the activation and download requirements before you begin.
Check activation →Each platform shows what you can download today, read from the release registry. Pick the one you have and see the devices it covers.
Runs Language, Image and Video
Runs Language
Runs Language, Image, Video and Robotics control
Our own numbers, each shown with its model, device, workload and build. Measured on Apple Silicon across 4 models and on NVIDIA GPUs across 5 models. Compare only runs that share a matching protocol.
Decode speed
197.9tok/s
Qwen3.6-35B-A3B on GeForce RTX 3090
GPU memory in use
21.44GiB
Qwen3.6-35B-A3B on GeForce RTX 3090
Decode speed
54.9tok/s
Qwen2.5-7B on Apple M4 Pro
Explore VEIZIK for business: evaluate a compiler and runtime stack that controls model execution, memory and scheduling on supported hardware.
Explore VEIZIK for businessSelect your platform to see available packages, requirements and the next steps.
Basic is over. Veizik begins.
Powered by Wan-AI/Alibaba. Powered by Stability AI. Model weights are licensed by their publishers; VEIZIK authors the inference engine only and neither redistributes nor relicenses them.