Generative AI on a Raspberry Pi.
A generative image, video or language model usually assumes a GPU and gigabytes of memory. veizik runs the same models to completion on a Raspberry Pi — on the CPU alone — by carrying the weights in a sub-byte format, executing them with a compile-free native kernel path, and streaming them through a bounded working set. The figures are measured on the real boards.
A GPU’s job, done on four CPU cores.
What makes a generative model fit and finish on a board with no accelerator.
- The same engine, on the CPU. There is no separate “mobile” build. The engine executes the model natively on the board’s Arm cores, vectorised for NEON, with the whole pipeline — text encoder, the diffusion or language model, and the decoder — running on the CPU.
- Sub-byte quantization. veizik’s own compact weight format carries the model in well under a byte per weight, so a model that would not fit in a few hundred megabytes does — and the smaller numbers are faster to move and multiply on a CPU, not just smaller to store.
- No compile step at run time. The GPU-free kernel path is built ahead of time for the exact core, so the first token and the first image come back without waiting on a compiler on the device.
- A bounded working set. The engine streams the model through a fixed amount of memory instead of holding all of it at once, which is what lets a 512 MB Raspberry Pi Zero 2 W finish a job it could not otherwise hold.
- One binary, no framework. The same self-contained engine as everywhere else — no Python, no deep-learning framework, no numeric library — so the dependency list on a Pi is the engine and nothing else.
The best compact format for each stage, chosen per model.
veizik’s own measured on-device figures — one moat format per stage, selected automatically.
veizik does not carry a model at one fixed precision. For each model and each stage — prefill, decode, quality, memory — the engine selects the compact format that measures best on that board and injects it with no conversion step, so the ladder costs nothing at run time. The formats below (lut4, lut5, vzint5, vzint6, vzint7, static_u8) are veizik’s own sub-byte weight formats, not generic integer widths; each row is the one the engine chose for that stage.
Single-board — available now
| Device | Model | Stage | Format | veizik measured |
|---|---|---|---|---|
| Raspberry Pi 5 | GPT-2 124M | decode | lut4 | 119 tok/s |
| Raspberry Pi 5 | GPT-2 124M | quality (PPL80) | lut4 | 31.6 |
| Raspberry Pi 5 | GPT-2 124M | peak memory | lut4 | 110 MiB |
| Raspberry Pi 5 | SmolLM2-135M | decode | lut5 | 109.7 tok/s |
| Raspberry Pi 5 | SmolLM2-135M | prefill (512 tok) | lut4 | 747 tok/s |
| Raspberry Pi 5 | SmolLM2-360M | decode | vzint6 | 37.2 tok/s |
| Pi Zero 2 W | SmolLM2-135M | decode | vzint5 | 17.7 tok/s |
Measured on the live Raspberry Pi build (language and on-device vision are public today). Every figure is veizik’s own, taken on the board; the per---mode ladder and the sample renders are on the edge page.
Mobile — measured, deployment pending
| Device | Model | Stage | Format | veizik measured |
|---|---|---|---|---|
| Exynos 9825 | GPT-2 124M | decode | lut4 | 266.9 tok/s |
| Exynos 9825 | SmolLM2-135M | decode | lut4 | 232.5 tok/s |
| Exynos 9825 | MobileNet V1 · classification | inference | static_u8 | 4.23 ms |
| Exynos 9825 | SSD-MobileNet V1 · detection | inference | static_u8 | 10.2 ms |
| Exynos 2600 | EfficientNet-B0 · classification | inference | vzint6 | 3.33 ms |
| Exynos 2600 | ConvNeXt-Tiny · classification | inference | vzint7 | 8.5 ms |
On-device on the Galaxy phones (Exynos 2600 / 9825), language and a broad vision set — confirmed on the phones and awaiting deployment (not yet downloadable). Deployment pending The full coverage is on the models page.
Measured on the boards, with the renders.
Every figure here is taken on a real Raspberry Pi; the numbers and the generated images and video are on the edge page.
The edge page carries the measured per-model figures (SDXS in about five seconds on a Pi 5 CPU, the full Stable Diffusion 1.5 in seconds with a few-step LCM, a language model on a 512 MB Zero 2 W) and the renders they produced; the gallery shows the output beside the datacenter and Apple Silicon work. The language and on-device vision models are available now — curl -fsSL https://veizik.com/rpi/install.sh | sh; image and video are in preview, released one at a time.
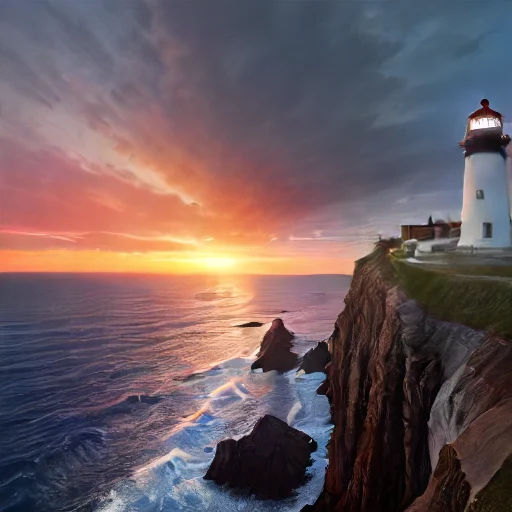
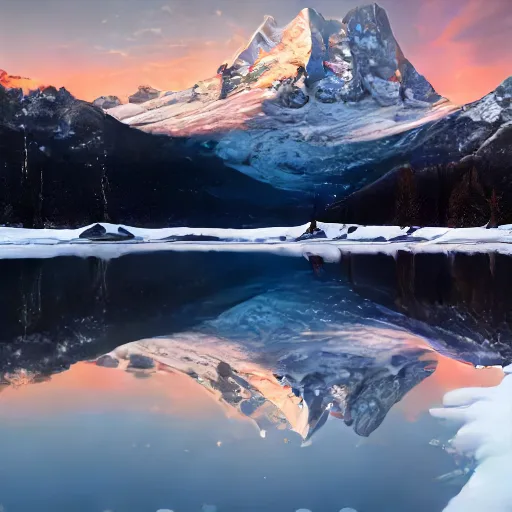
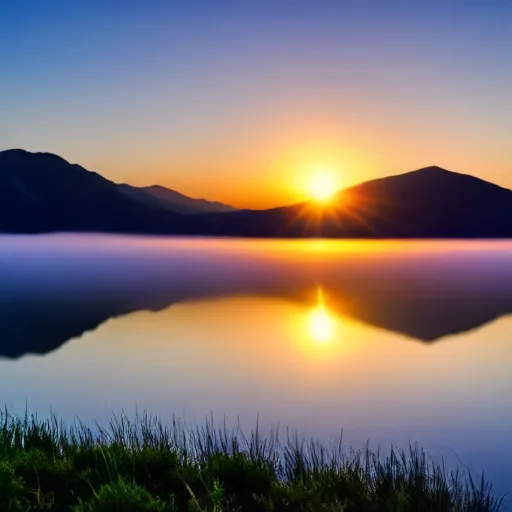
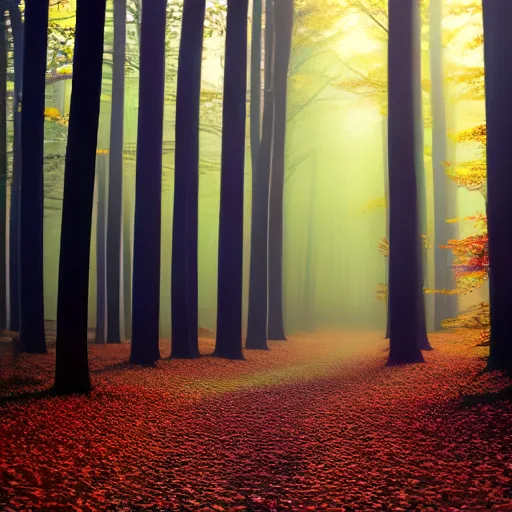
Shown as what the engine draws on the named board — output, not a benchmark; no speed figure is attached to these images. Each was rendered by Veizik natively on the Raspberry Pi shown, from a published checkpoint, with no GPU in the loop.
The same engine, all the way down.
- It runs where there is no GPU and no cloud. On-device from the checkpoint, so the data never leaves the board and there is no account, no network and no per-image cost.
- It fits the hardware you have. From an 8 GB Raspberry Pi 5 down to a 512 MB Zero 2 W — the memory budget is a setting, not a wall.
- Image, video and language, from one engine. The same binary that runs a datacenter GPU runs a Pi; only the model and the memory budget change.