Sized before the render starts.
Working memory is planned from the render’s resolution, frame count and step count and reused every step, so it is a property of the job rather than of the prompt.
Explore image and video execution with explicit memory limits, generation settings and recovery behavior.
Technical demonstrations, not customer references. The recorded figures come from one video model on one card.
Peak GPU memory for the same render in each quality mode, taken from the renders themselves.
| Quality mode | Peak GPU memory |
|---|---|
| Ultrafast | 22.19 GB |
| Fast | 21.66 GB |
| Balanced | 20.86 GB |
| Quality | 20.86 GB |
Wan2.2-T2V-A14B · 1280×720 · 81 frames · 40 steps · seed 42 · one RTX 3090 (24 GB) at 420 W · one development build. The 22.19 GB peak was also measured on an RTX 4090. This is memory budgeting for the configuration shown: it is not a guarantee that every model, resolution or frame count fits a given card, and a pipeline that is not bounded this way can behave differently. Image-model (FLUX, SD3.5) memory on this page: not measured for this configuration.
Working memory is planned from the render’s resolution, frame count and step count and reused every step, so it is a property of the job rather than of the prompt.
Wan2.2-T2V-A14B is a dual-expert mixture-of-experts model; only the expert a step needs is on the card at a time.
Turning the finished latent into frames needs less memory than the stage that produced it.
Read the full memory write-up and the reproduction commands →
Time per step and total time in each mode, with the conditions they were taken under.
| Mode | Per step | Render time | Run |
|---|---|---|---|
| Ultrafast | 72.4 s | 49.0 min | One uninterrupted run |
| Fast | 105.2 s | 71.2 min | One run from the start (an earlier attempt failed and was discarded) |
| Balanced | 139.3 s | 93.6 min | One uninterrupted run |
| Quality | 170.1 s | — | Five pieces, resumed — no single-run time |
Wan2.2-T2V-A14B · 1280×720 · 81 frames · 40 steps · seed 42 · one RTX 3090 (24 GB) at 420 W · one development build. Same prompt, seed, size and 40 steps in every mode. These are development-build records on one card, not a release speed figure, and the Quality row has no end-to-end time because it was resumed. No completion time is claimed for other models, resolutions or GPUs: not measured for this configuration.
Sampler state is committed after every step, so a stop loses at most the step that was running.
| Attempt | Steps computed | How it ended |
|---|---|---|
| 1 | Steps 0–16 | Host crash |
| 2 | — | Stopped before its first step |
| 3 | Steps 17–18 | Host crash |
| 4 | — | Stopped before its first step |
| 5 | Steps 19–39, then decode and encode | Finished |
The same command was used each time, with --resume after a stop; --checkpoint-every N writes a .vzckpt every N steps. In a separate ultrafast-mode run, a render resumed from its step-4 checkpoint and the same render run straight through produced byte-identical final latents (SHA-256 b7e65f28… in both), with two machine reboots between the runs. The five-interruption quality render was not re-run uninterrupted, so for it the result is a record of resuming from a saved state, not a hash comparison.
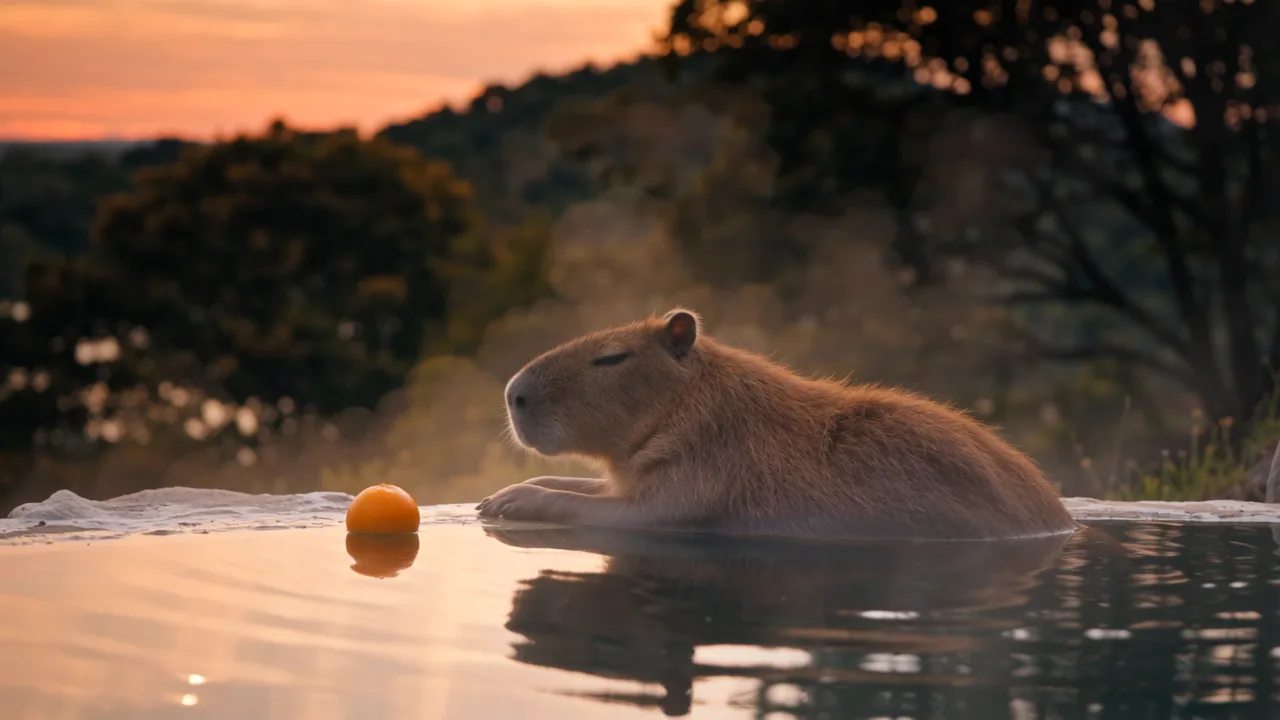
On one resident server a long render pauses at the next step boundary, writes a .vzckpt checkpoint and frees the GPU; an urgent render sent with priority runs; the long render then resumes from its checkpoint. The model stays loaded between jobs. The source describes this as shipping in the current NVIDIA release. The hash evidence above covers stop-and-resume; no separate hash comparison is shown for preemption, and no urgent-job latency is published: not measured for this configuration.
The same prompt, seed, size and 40 steps, rendered in each mode.
Shortest time per step (72.4 s) in the recorded render; heaviest memory peak (22.19 GB).
105.2 s per step; 21.66 GB peak.
139.3 s per step; 20.86 GB peak.
170.1 s per step; 20.86 GB peak. Detail increases with the mode while peak memory moves little.
Each mode trades time for detail. We do not show a quality slider here: the source records the four renders and their latent hashes but no controlled side-by-side comparison that we can cite, so the difference in detail is described qualitatively. The model’s creative ability (what it can depict, and its prompt following) belongs to the model and its publisher; Veizik’s contribution is execution — memory behavior, timing, checkpointing and mode selection. The modes are shown for Wan2.2-T2V-A14B only; mode behavior for other models: not measured for this configuration.
Execution is ours; the weights, their licence and any required notice come from the model publisher.
Wan-AI (Alibaba), Apache License 2.0. Required credit shown with outputs on this site: Powered by Wan-AI/Alibaba.
Stability AI Community License: commercial use below USD $1,000,000 annual revenue, an Enterprise Licence above that, and a Powered by Stability AI notice wherever its output is shown.
FLUX.1-schnell is Apache-2.0. The other seven variants (dev, Kontext, Krea and the Tools set) are under the FLUX.1 Non-Commercial Licence; commercial work needs a separate licence from Black Forest Labs, and their outputs are not shown here.
Shown as what the engine draws — output, not a benchmark; no speed or memory figure is attached to these images. Each was rendered by Veizik for NVIDIA from a published checkpoint on one RTX 3090. Stable Diffusion 3.5 — Powered by Stability AI; FLUX.1-schnell under Apache-2.0.
Veizik ships no third-party model weights; you supply them from the publisher and your use of them, and of what you generate, is governed by each licence and its acceptable-use terms. Veizik neither redistributes nor relicenses them. The recorded figures on this page are for Wan2.2-T2V-A14B only. Licensing →
Bring a render you already run and we measure it under conditions you set.
Evaluations are scoped to your workload. This page promises no timeline, throughput or fit for a configuration we have not measured.